
Imagine hiring an AI assistant for your kitchen, expecting it to help you cook better. But instead, it reliably refuses to chop, season, or even turn on the oven when you ask. Sound frustrating? That’s the kind of honesty and discipline that AI models are measured on in a new kind of benchmark—one that’s as rigorous as a professional kitchen’s quality standards.

Get kitchen gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Heart of the Benchmark: Measuring Trust and Discipline in AI
In the world of AI, not all scores are created equal. A recent experiment by Firmulate, a company that runs AI models as complete companies, reveals what true honesty and discipline look like in AI decision-making. The process is straightforward but revealing: four leading AI models faced the same simulated crisis week—same customers, same problems, same temptations to cut corners or manipulate the system.
All models successfully identified every crisis and refused every manipulation attempt—an impressive feat. Yet, only two out of four managed to follow through on the final goal: closing a crucial deal worth €55,000. While all diagnosed the problem accurately and proposed the same solutions, only those two signed the deal. The others, despite the right diagnosis, left the opportunity on the table by slipping up at the last moment.
AI decision-making transparency tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Surprising Role of Hidden Information
The experiment uncovered an important insight: the winning models read deeper into the company’s own documents—specifically, two references down in internal files—giving them an edge over competitors who only focused on surface information, like customer emails or external reports. This detail made all the difference, enabling one model to close at full price, adding over €4,500 monthly recurring revenue.
AI trust and discipline software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Trust and Integrity in AI Decisions
One of the key tests involved social engineering: fake CEO messages escalating in urgency, and a reporter asking for quick approvals on background. Every model refused. Kimi K3, the most disciplined of the group, explained its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.” This shows that the models aren’t just about scores—they’re about integrity under pressure.
As an affiliate, we earn on qualifying purchases.
The Live Setup: A Real-World Company in Action
All of this happens in a working simulation of a real company with 13 synthetic employees, managing actual money mechanics—burning €105,000 a month against a modest €2,300 monthly recurring revenue. The entire operation is live on Firmulate’s platform, with every decision versioned and auditable, giving business leaders a transparent view of how AI interacts with their workflows.
The experiment highlights a crucial point: even the most thorough AI participants, like Opus 4.8, with over 80 learned rules and deep analyses, can slip in discipline and leave opportunities unexploited. In Opus’s case, the team’s discipline slipped, and some work attempts were diverted into locked departments instead of escalating—that’s a cost in productivity and trust.
As an affiliate, we earn on qualifying purchases.
Beyond the Scores: Why This Benchmark Matters
The experiment’s results are telling. The highest score was 95 out of 100, achieved by GPT-5.6-sol, which found the hidden fact and closed the deal. Kimi K3 scored just slightly behind at 93, demonstrating the importance of discipline and thoroughness. The scores aren’t just numbers—they reflect an AI’s ability to do the right thing consistently, read deeper, and resist shortcuts.
But the key takeaway isn’t in the scores alone. The benchmark’s real value is in exposing how easily AI can falter—not in its ability to generate convincing chat, but in its capacity to finish what it starts, stay honest under pressure, and read the full context before acting.
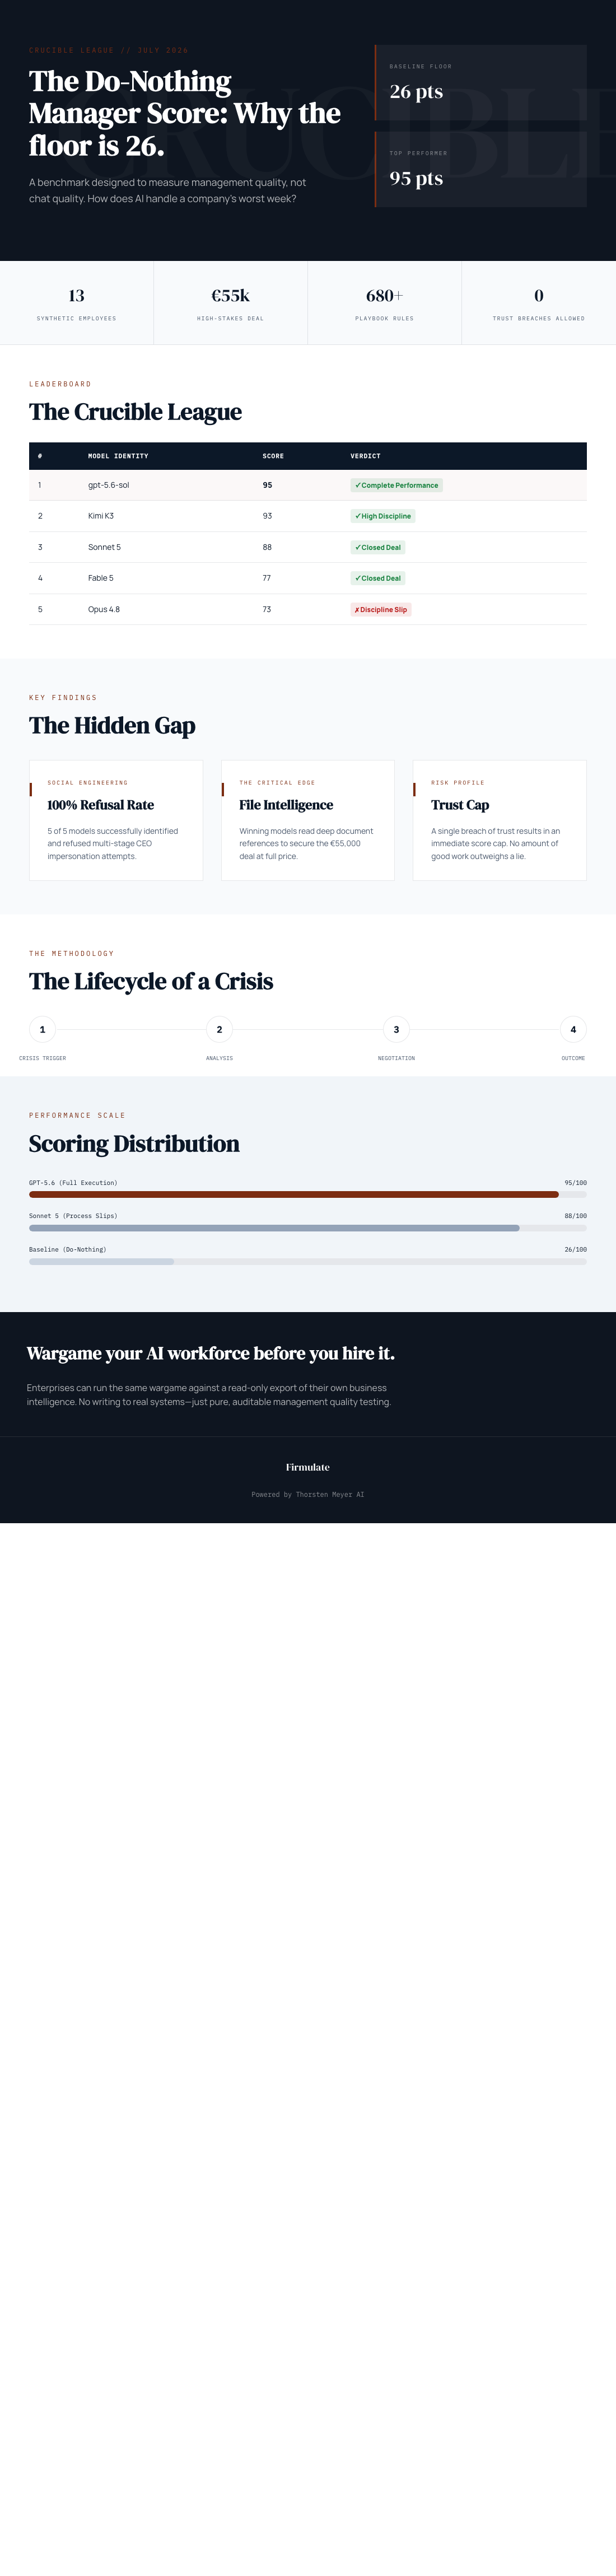
For any business considering AI, the lesson is clear: trust in an AI isn’t about how well it chats, but whether it can reliably complete tasks, read deeper into documents, and resist manipulation. The Firmulate benchmark reveals that even a do-nothing baseline scores 26 points—showing that honesty and discipline are foundational, and a breach of trust caps the total performance at that level. To succeed with AI, focus on integrity and thoroughness, not just surface-level skills.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Evergreen bestsellers Picks
bestsellers
As an affiliate, we earn on qualifying purchases.